Provisa / Sources
Connect your databases, APIs and files. Query in 5 minutes.
Any SQL database. Any REST, GraphQL, gRPC or OData API. Any file or object store. Your own code in Node, Python, Go or Rust. Each becomes a governed table you query where the data already lives, joined to everything else, and you copy data only when you declare a copy.
A long list of logos proves little on its own, so here is how the list is built. Today that means 82 connectors reaching over 200 named sources.
Four classes of source
Any SQL database
PostgreSQL, Snowflake, Oracle, BigQuery and the rest of the SQL family. The query engines read them natively.
Any API
REST with an OpenAPI description, GraphQL, gRPC and OData. Provisa reads the API's own description to find its tables.
Any file or object store
A folder, a bucket, an SFTP host or a SharePoint site. CSV, Parquet, Excel and the tables inside documents.
Your own code
A function in Node, Python, Go or Rust that returns rows. It becomes a table like any other.
One contract, a tree of connectors
Every connector answers the same questions. Which tables and columns does the source have, with what types and descriptions? How are rows read? Which filters can it take? What does it need to connect, and how does it sign in? Does it run inside Provisa or on a host of its own? Those answers are the source contract.
Four runtimes implement the contract, one each for Node, Python, Go and Rust. On those runtimes sit a handful of bases: OpenAPI and REST, GraphQL, gRPC and OData. A named source such as Stripe or Jira is one of those bases plus a short configuration giving its URL, how it signs in and a few fixed values. Hand-built connectors are kept for the few sources whose logic fits no base.
The other root is everything the query engines read natively, with no runtime in between: SQL databases and warehouses, files and lakes such as Parquet, Delta and Iceberg, and stores like MongoDB, Kafka and Elasticsearch.
Every connector inherits its base's tests
Each base has a conformance suite, and every connector built on that base inherits it. Discovery, types, paging, the filters it accepts, sign-in and errors are tested once, at the base. A named source's own tests then cover only what it adds, its configuration and any overrides.
So the two-hundredth source on a base is held to the same bar as the first one.
A page for every source
Each named source has a page generated from its definition. It shows the base the source is built on, what Provisa pushes down to it, what you need to connect, and when it was last verified against a live account. Where no live check has run yet, the page says when the source last passed its base's suite.
Nobody writes these pages by hand, so they can't drift from what the connector does.
Not on the list? Write it in 15 minutes
Write a function in Node, Python, Go or Rust that returns typed rows, and it becomes a table. It gets the same catalog entry, governance, hosting and protocols as every named source. Visibility, masks and row rules apply to what it returns, you can join it to the rest of the model, and SQL, GraphQL and Cypher clients all reach it. Its code is pinned by version, commit or hash, so it is promoted with the model.
Run it inside Provisa, or on a host of its own beside the data, on a GPU box or inside another network. Provisa builds the container image for you and pairs with it over mutual TLS.
Today: 82 connectors
Here is the tree as it stands, grouped the way the product's source picker shows it. Those 82 connectors reach over 200 named sources, and the list grows one short configuration at a time.
Enterprise
- SharePoint
- Salesforce
- ServiceNow
- Jira
- QuickBooks Online
- Cloud Inventory
- Google Workspace
- Microsoft 365
- GitHub
- GitLab
- Shopify
- Stripe
- OpenMetadata
- DataHub
- Splunk
Subscriptions
- AskAmerica
- Kaggle
RDBMS
- PostgreSQL
- RDS
- Aurora
- Cloud SQL
- AlloyDB
- Azure
- Supabase
- Neon
- MySQL
- SingleStore
- MariaDB
- SQL Server
- Oracle
- DuckDB
- Exasol
- SAP HANA
- CockroachDB
- YugabyteDB
- Greenplum
- TiDB
- Firebird
- HiveServer2
- JDBC
Cloud DW
- Snowflake
- BigQuery
- Amazon Athena
- Databricks
- Redshift
- Microsoft Fabric Warehouse
- Azure Synapse SQL
- MotherDuck
Analytics
- ClickHouse
- Elasticsearch
- Apache Pinot
- Apache Druid
- Trino / Presto
Data Lake
- Delta Lake
- Apache Iceberg
- Hive Metastore
- Hive on S3
NoSQL
- MongoDB
- Azure Cosmos DB
- Qdrant
- Cassandra
- Redis
Code Resolvers
- Node.js
- Python
- Go
- Rust
Graph
- Neo4j
- SPARQL
- Wikidata
File
- SQLite
- CSV File
- Parquet File
- File Crawler
- CSV
- TSV
- JSON
- YAML
- Excel (XLS, XLSX)
- Parquet
- Arrow
- HTML
- Markdown
- DOCX
- PPTX
- Log files
- Wikipedia
Other
- Google Sheets
- Prometheus
- Airport
API
- REST API
- dbt
- GraphQL
- gRPC
Streaming
- Kafka
- WebSocket Feed
- RSS / Atom Feed
- Ingest
Data Quality
- Soda
- Great Expectations
- Data Profiler
The file crawler
Eighty-two connectors, and one of them finds the rest of your data. Seventy-nine of them connect to a system you already know you have. The eighty-second is a crawler, and it tends to find the half of your estate nobody put on the inventory.
It is one source type, and the only one where you register a location rather than a system. Point it at a folder, a bucket, an FTP or SFTP host, or a SharePoint site and it walks the tree recursively, looking for database files and for files with tabular data embedded in them. What it finds gets cataloged as an available table; registering it is still your call, the same as for any other source.
A CSV or Parquet file is a table. In an Excel workbook it looks through each sheet, finds the regions that look like tables, and extracts each one. In HTML, Markdown, Word and PowerPoint documents it extracts the tables the document marks as tables. In documents with links it follows them too, from each start URL down to a configurable depth, so it works well over websites and documentation portals.
Where it crawls
- Local & network folders
- S3
- SharePoint
- HDFS
- HTTP(S)
- FTP · FTPS
- SFTP
- Iceberg
What it reads directly
- CSV
- TSV
.gzof either- JSON
- Parquet
- Arrow
- YAML
- SQLite ·
.db
What it converts to tables
- Excel ·
.xlsx·.xls - Word ·
.docx - PowerPoint ·
.pptx - HTML
- XML
- Markdown
The data that runs a department often sits in a share drive and has never been near a governance program. Finding it used to be a project. Once found, what you register lands under the same row-level security, masking and relationship rules as the databases.
Systems that aren't databases
Connect SharePoint and its lists enumerate as schemas you can query. Run a Splunk search and the results come back as a table you can JOIN to your business data. A live Google Sheet is a table, and so is a REST, GraphQL, gRPC, WebSocket or RSS endpoint, registered as a governed table that cross-source joins reach like any other.
Shaping takes a declaration instead of a program
Non-relational data is where pipelines are born: the response is nested, the document has an array inside it, the location is a pile of files, so somebody writes code to flatten it and a procedure enters the path permanently. The variety is smaller than it looks. There's a modest set of structure types, each with a short declarative rule for projecting it into rows and columns: the path to the collection and the fields to lift from it, a sampled document schema with the steward's explicit types overriding what was inferred, or a crawled location that catalogs what it finds. Once it's flat, everything after it is SQL, which a machine can read back.
Why that removes the downstream painGraph and RDF are first-class
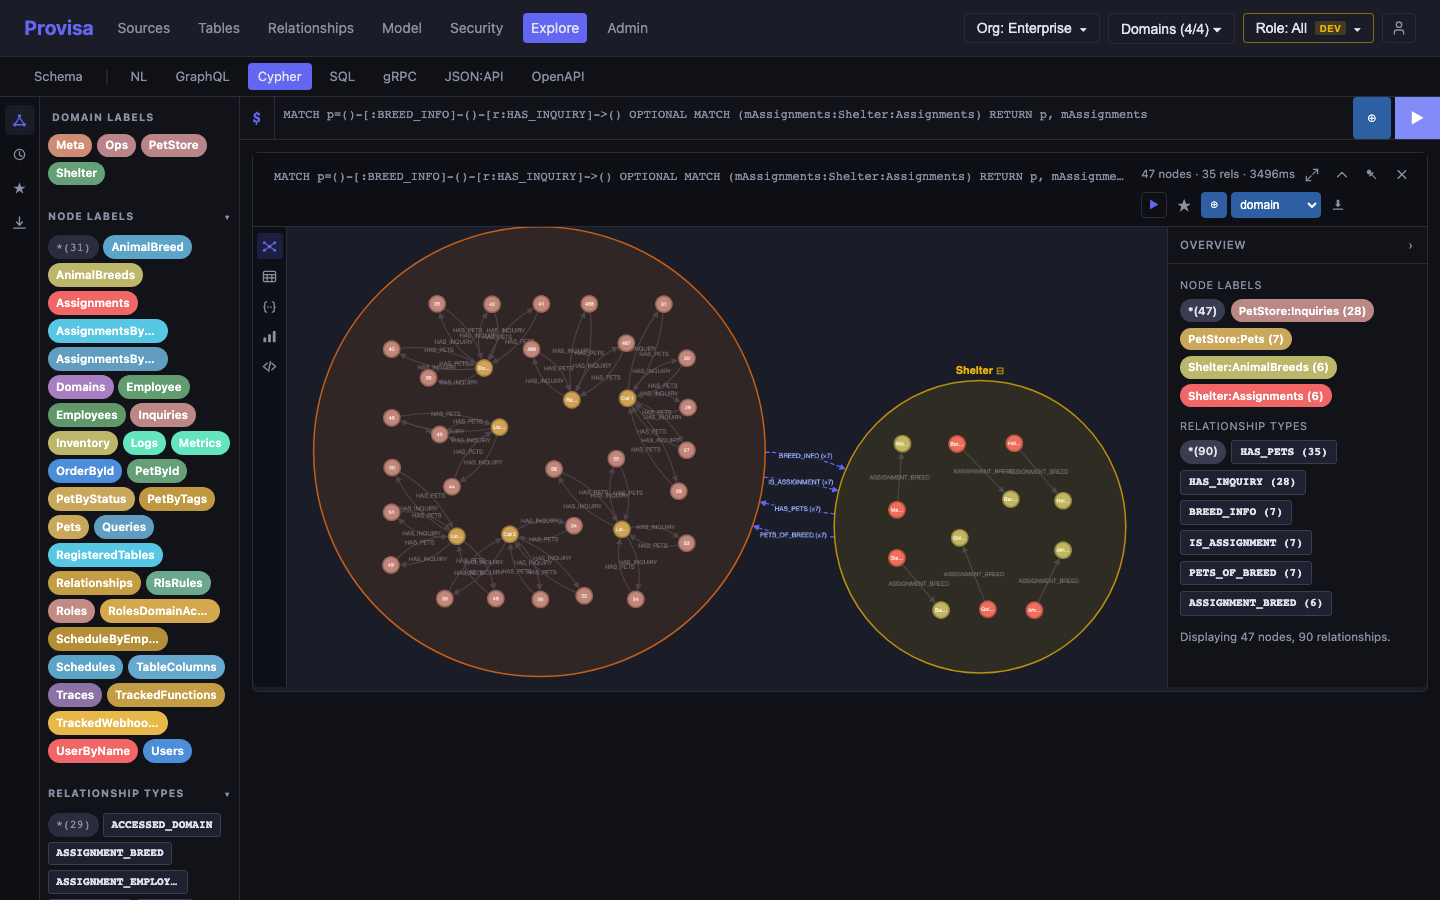
Neo4j and SPARQL sources take part in the same model, the same relationship registry and the same access-control layers as the relational ones. So a Cypher traversal across a relational source and a graph source is one legal query, not two queries and a join in application code.
The 82
Every registrable source type, grouped by what it is. Each one registers the same way and lands under the same governance; the per-type connection fields are in the source reference.
Enterprise SaaS
- Salesforce
- ServiceNow
- Jira
- Stripe
- GitHub
- GitLab
- SharePoint
- Splunk
Relational
- PostgreSQL
- MySQL
- MariaDB
- SingleStore
- SQL Server
- Oracle
- Firebird
- SQLite
- CockroachDB
- YugabyteDB
- Greenplum
- TiDB
- SAP HANA
Warehouses & lakehouses
- Snowflake
- BigQuery
- Databricks
- Microsoft Fabric
- Synapse
- Redshift
- Trino
- Delta Lake
- Iceberg
- Hive
- Hive on S3
- HiveServer2
Analytics & OLAP
- ClickHouse
- DuckDB
- Elasticsearch
- Apache Pinot
- Apache Druid
- Exasol
Graph & semantic
- Neo4j
- SPARQL / RDF
NoSQL, cache & streaming
- MongoDB
- Cassandra
- Redis
- Kafka
- WebSocket
- RSS
Files & documents
- CSV
- Parquet
- Google Sheets
- File crawler
- Kaggle datasets
APIs & remote schemas
- REST / OpenAPI
- GraphQL remote
- gRPC remote
- Airport (DuckDB)
Observability & other
- Prometheus
- Splunk
- Soda
- Great Expectations
- Ingest
- Data profiler
- Cloud inventory (Azure · AWS · GCP)
- Government data
Observability as data
Traces, metrics, and logs are collected via OpenTelemetry, compacted into Iceberg, and registered as queryable tables, so the audit trail is a source like any other, joinable to the business data it describes.